Run 50,000+ Open Models Through One Inference API
Pick a model, get an LLM API key and start building in minutes. No GPUs to provision, models to deploy or infrastructure to manage.
 Official Hugging Face inference provider
- OpenAI-compatible API
 Backed by AMD and Airbus
- 50,000+Open models
- 256KContext window
- <5minTo your first API call
 GLM 5.3
 Kimi K3
 DeepSeek V4.1 Flash
 Qwen 3.8 (27B)
 MiniMax M3.1 Flash
 Gemma 4 (31B)
- Qwen/Qwen3.8-27B$3.00 out


Self-hosting or a serverless GPU vs the Featherless LLM API
Hosting an LLM means renting, running and paying for GPUs. Featherless takes that off your plate.

Getting started
Rent a GPU, set up a server and container
Get an API key
The model
Download and load the weights
Pick from 50,000+ models
Waiting
Cold starts when workers scale from zero
No cold starts on popular models
Traffic spikes
You size GPUs and set autoscaling
We handle the GPUs
The bill
Every hour the GPU runs, busy or idle
Per token, only for requests that succeed
First response
Once setup works
Seconds after your first call
Sign up now and make your first API call in <5 minutes
Get your API key
One open source LLM API for 50,000+ models
Find every major open model family, plus thousands of fine-tunes and community variants. Switching models is a one-line change.
GLM 5.3Kimi K3DeepSeek V4.1 FlashQwen 3.8 (27B)MiniMax M3.1 FlashGemma 4 (31B)Prices per 1M tokens from api.featherless.ai/v1/models, checked 6 November 2026.
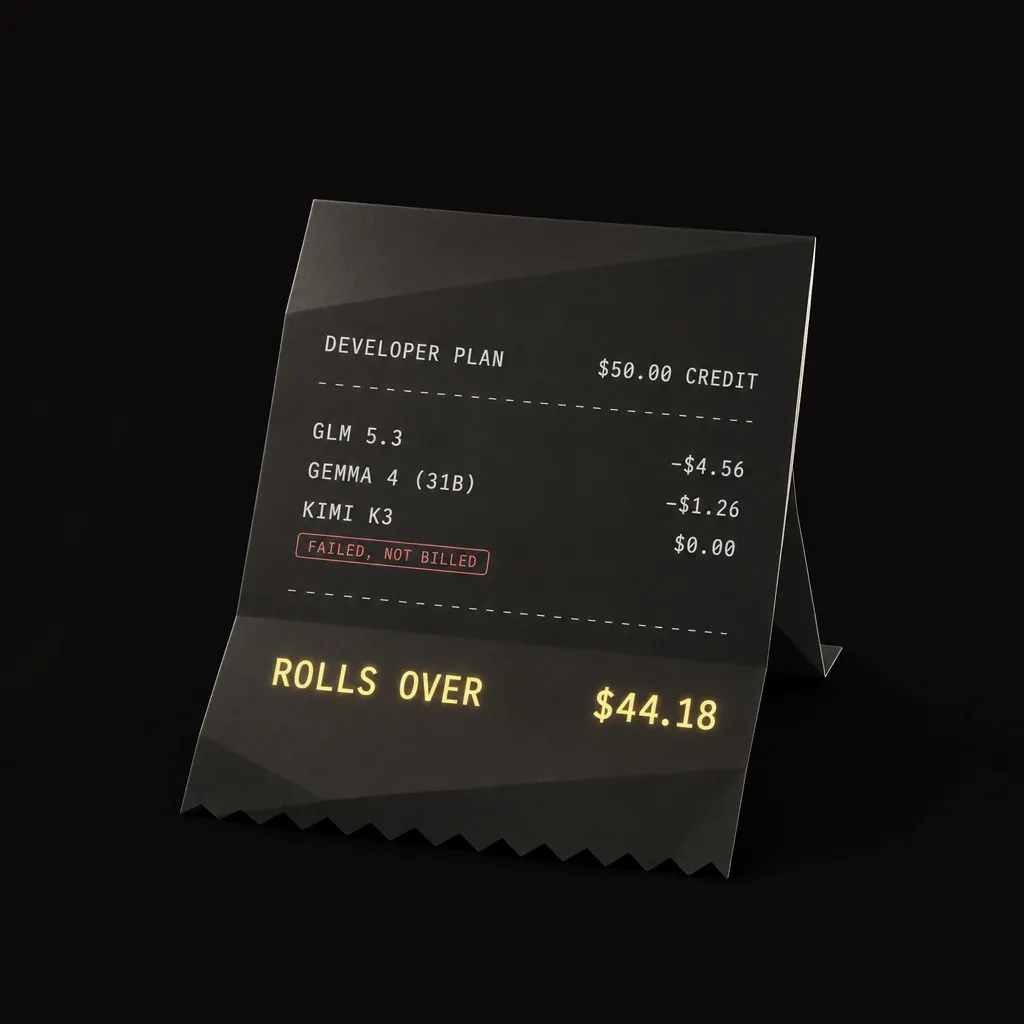
Start building for $50 a month. Cancel anytime
Each model has its own price per million tokens, drawn from your monthly credit.
- $50 of credit a month on the Developer plan.
- Unused credit never expires and rolls over to the next month.
- Failed requests cost nothing.
- No surprise bills. Calls pause when your credit runs out.
3 steps to an open model running in your app
- 1Get your API keySign up and create a key from your dashboard.
- 2Pick a modelPick any of 50,000+ open models, new releases included, and copy its ID.
- 3Change two lines and shipSwap the base URL and API key in your OpenAI SDK. We handle the rest.
Also works with Cline, OpenHands and n8n.
- google/gemma-4-31B-it
- Qwen/Qwen3.8-27B
- zai-org/GLM-5.3
- moonshotai/Kimi-K3
- deepseek-ai/DeepSeek-V4.1-Flash
- MiniMaxAI/MiniMax-M3.1-Flash
Private LLM hosting on GPUs reserved for you, run by our engineers
For steady volume, private fine-tunes or a latency SLA, get dedicated GPUs that only your team uses. Keep your API key and your code exactly as they are.
- Dedicated H100, MI325X, B200 or B300 GPUs
- Named engineers who tune and run them, with an SLA
- Bursts to the public pool on the same API key
Serverless inference API questions
Is Featherless really serverless?
Yes. There are no GPUs to provision, no containers to build and no weights to download. You send a request to an OpenAI-compatible endpoint, and we handle GPU assignment, loading and scaling. Popular models are already loaded, and less-used ones load when they're first requested.
Which models can I use?
Any of 50,000+ open models, including GLM, Kimi, DeepSeek, Qwen, MiniMax, Gemma and thousands of community fine-tunes, with sizes up to 2.8T parameters. Switching models means changing one string in your request.
Will it work with my existing code?
If your code calls the OpenAI API, change the base URL and the API key and you're done. Featherless also works with Cline, OpenHands, n8n and your own agents.
How am I billed?
The Developer plan gives you $50 of credit each month, drawn down per token at each model's own input and output rate. You only pay for successful requests. Unused credit never expires, and you can top up whenever you like.
Can I run my own fine-tuned model?
Yes. On the Developer plan, private fine-tunes are served through Hugging Face. If you need a fine-tune on dedicated hardware, the Business plan covers that.
What happens when my traffic spikes?
The Developer plan includes 100 concurrent units with priority capacity. Larger models use more units per request, up to 4. If a model is briefly at capacity, you get an HTTP 503 and nothing is billed, so you can retry or switch models. If you regularly need more headroom or guaranteed latency, that's the point to look at dedicated GPUs.
Do you store my prompts or outputs?
No. Prompts and completions are never stored, on any plan.
When should I move to dedicated GPUs?
When your volume is steady, you need a latency SLA, or you want private fine-tunes on isolated hardware. Business gives you dedicated H100, MI325X, B200 or B300 GPUs, named engineers and an SLA, with burst to the public pool on the same key. Request a dedicated node and we'll size it with you.